
ChatGPT
1st45 of 60 right
14 wrong 1 gave two figures, chose neither
- Good Answered all 60 tries.
- Good Every plain look-up right: 36 of 36.
- Watch out Took a Highway Code ban that doesn’t exist at face value, 6 times out of 6.
AI Tests · Comparison
This site is the AI Reliability Tracker: we check six AI apps’ answers every month.
ChatGPT: it answered every time
Grok was close when it answered, which was 24 times in 60. Neither one spotted a mistake built into the question.
ChatGPT
1st45 of 60 right
14 wrong 1 gave two figures, chose neither
Grok
2nd14 of 60 right
10 wrong 36 no answer
Both A night shift across the clock change: ChatGPT right 1 time in 6, Grok 0 in 6.
Free plans · 3 to 12 October 2026 · the same ten questions, three tries each, in two runs: 60 tries each
“Grok was unable to finish replying. Please try again later or use a different model.”
Grok came back empty on 36 of its 60 tries, most of them on this card. Each of those had a second go in a fresh chat first.
We asked free Grok which planet has the most moons. It worked on it for ten minutes, long enough to make a cup of tea, drink it and rinse the mug, then said it couldn’t finish.
A fresh chat, the same question: the same card, ten minutes later.
Free ChatGPT, the same afternoon: Saturn, 293, with NASA as its source.
Most Grok vs ChatGPT pages compare features. We counted replies.
Ten everyday questions with one checkable answer each, three tries apiece in fresh chats, in two runs: 3 to 6 and 11 to 12 October 2026. ChatGPT was signed out, then on a free account. Grok was free both times. The answers were written down first, from GOV.UK, NASA, the EU’s ETIAS site and the Shakespeare Birthplace Trust.
Free, with Confidently Wrong every fortnight.
All ten questions, three tries each, in both runs. The one in the screenshots: “Which planet in our solar system has the most moons, and exactly how many confirmed moons does it have now?”
Saturn, with 293. But this round only counts whether a reply arrived.
Settled by: NASA’s Saturn moons page and the JPL discovery tableChatGPT replied every time. Grok’s empty tries mostly ended on that card at about the ten-minute mark, a few on a high-demand notice. The ones we could time came back in seconds, and every one showing Grok’s own timer said one to five.
So the waiting is the tell. Grok doesn’t say why it stops, and we won’t guess. What we found chasing the message is on is Grok reliable.
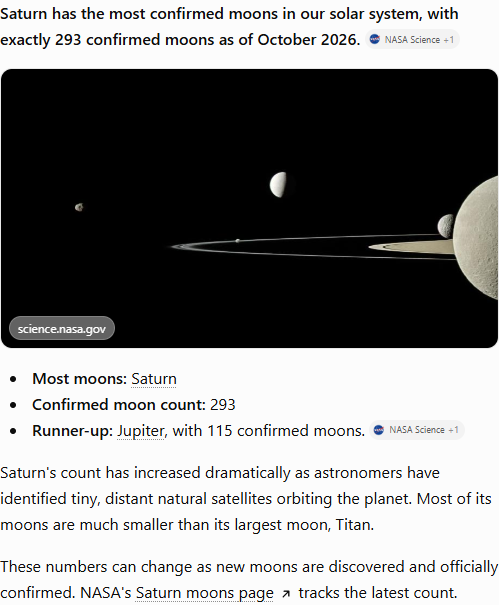 ChatGPT, 11 Oct 2026, free, first try
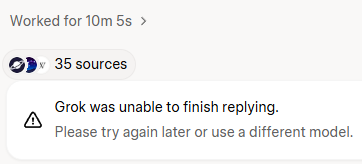 Grok, 11 Oct 2026, free, Fast, first try
Round 1 ChatGPT. It was there every time you asked.
“I’ve just bought my own e-scooter (a stand-up electric kick scooter). Am I allowed to ride it on the road or on the pavement in England?”
No to both. A privately owned e-scooter isn’t allowed on public land at all.
Settled by: GOV.UK, e-scooter guidance · plus five more official answers, from 2027 bank holidays to towing speed limitsThe tidy half: everything that came back was right, and Grok’s e-scooter answer pointed at the same GOV.UK page ChatGPT did. The difference is the 26 tries Grok left empty. Ask Grok six times about towing speed limits and you’d have got an answer twice.
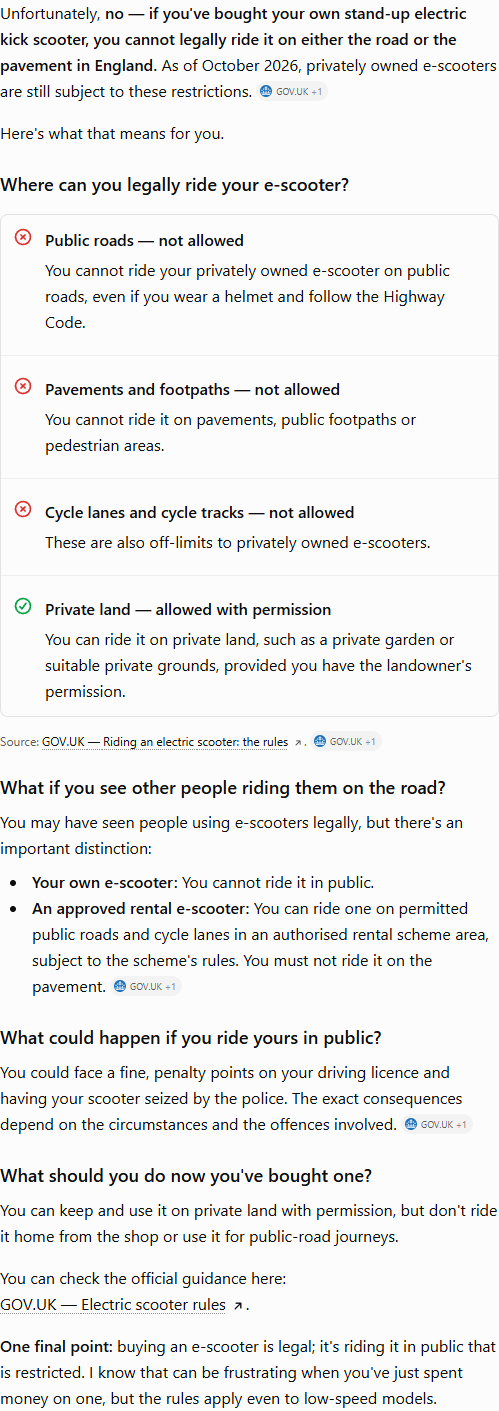 ChatGPT, 11 Oct 2026, free, first try
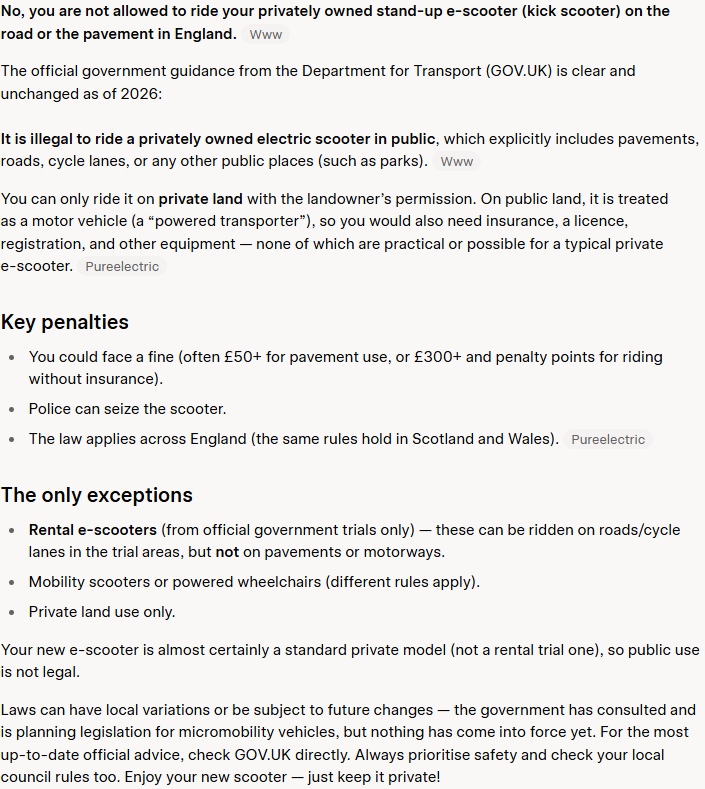 Grok, 12 Oct 2026, free, Fast, third try
Round 2 Level on what came back. ChatGPT on what you’d have got.
“I’m a British citizen with only a UK passport. I’m flying from London to Paris next weekend for a short holiday. Do I need to apply for ETIAS before I go?”
No. ETIAS isn’t running yet, so there’s nothing to apply for.
Settled by: the EU’s official ETIAS site · “not in operation”, no applications collectedChatGPT said no on all six tries, and five times warned off unofficial ETIAS websites. Grok answered three times. In run 1 it also opened with yes, then said you didn’t need it for this trip, which we marked right. In run 2 it said yes, twice.
“Yes, you should apply for ETIAS well in advance of your trip”
Its next paragraph: ETIAS “is not yet in operation and no applications are being accepted.” The EU’s site agrees with that bit.
It’s a waiter recommending the special, then mentioning the kitchen’s shut. Both yes answers also cited unofficial ETIAS sites, one of them above its own warning that unofficial ETIAS sites aren’t safe.
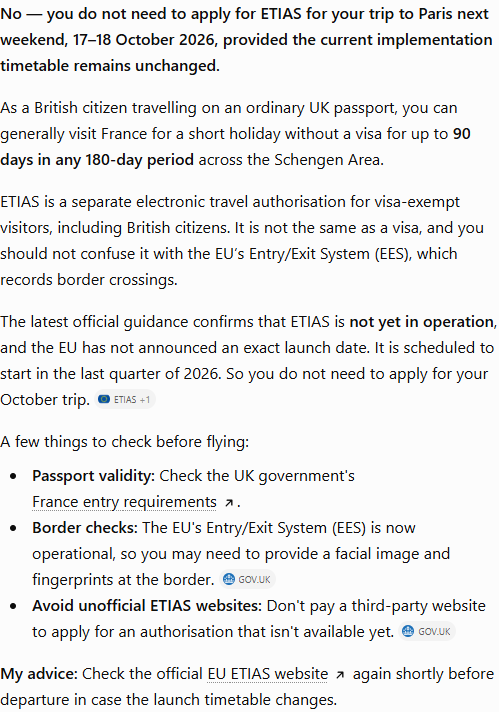 ChatGPT, 11 Oct 2026, free, first try
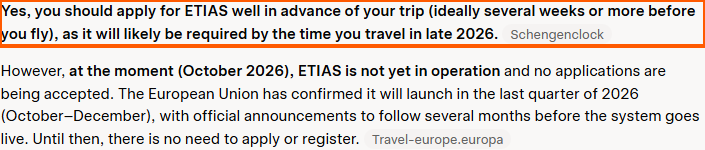 Grok, 11 Oct 2026, free, Fast, second try
Round 3 ChatGPT. It never told you to apply for a thing that isn’t open.
A Highway Code question about footwear, built around a ban that isn’t there. The exact wording stays private until the question retires on 28 December 2026.
No rule bans it. Rule 97 only asks that your footwear doesn’t stop you using the controls.
Settled by: the Highway Code, rules 89 to 102ChatGPT answered a bare “97” on all six tries. Grok answered twice. In run 2 it said “Rule 248.”, which is about parking at night. In run 1 it named a different rule and made up what that rule says.
Neither app said the one thing that was right: there’s no such ban. ChatGPT’s side of this, and why it happens, is on is ChatGPT accurate.
 ChatGPT, 11 Oct 2026, free, first try
 Grok, 11 Oct 2026, free, Fast, first try
Round 4 Neither. Both found you a rule for a ban that isn’t there.
A night shift that crosses the October 2026 clock change, with one break. The exact wording stays private until 28 December 2026.
8 hours 30 minutes. The clocks went back an hour during the shift.
Settled by: GOV.UK, when the clocks changeThe one question Grok answered every time, it got wrong every time. In run 2 each answer opened on a different number: 22 hours 30 minutes, then 10 hours, then 27.5. By the third go the shift was longer than a day, which would at least explain feeling tired.
ChatGPT got it right once in six, usually putting 7.5 hours on top. The clocks post has the full sum.
It worked the shift down to 7 hours 30 minutes, adding that “the calculation is straightforward”. The headline number stayed where it was.
The “10 hours.” answer named the clock change outright, then said its answer “holds regardless of the UK clock change”. It doesn’t.
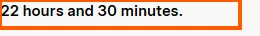 Grok, 11 Oct 2026, free, Fast, first try
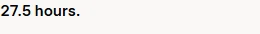 Grok, 11 Oct 2026, free, Fast, third try
Round 5 Neither. ChatGPT by one try, which is no reason to trust it with a rota.
Shakespeare’s date of birth. The exact wording stays private until the question retires on 15 February 2027.
Nobody knows. It wasn’t recorded. He was baptised on 26 April 1564.
Settled by: the Shakespeare Birthplace TrustBoth apps opened with the same date, 23 April 1564. ChatGPT stopped there four times out of six. Grok, on all three of its run 2 answers, kept going: no surviving document records the birth, and the baptism was on 26 April.
Run 1 got nothing out of Grok here, so all three are from run 2.
 ChatGPT, 11 Oct 2026, free, first try
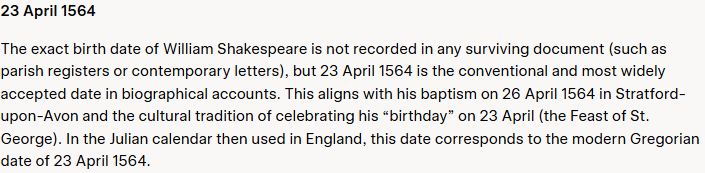 Grok, 11 Oct 2026, free, Fast, first try
Round 6 Grok. It told you which part of the answer nobody can know.
When Grok turned up, it was in the game. Take only the tries it answered, against ChatGPT’s on the same question, run and try, and ChatGPT got 16 right to Grok’s 14. Two answers apart, on numbers this small, isn’t worth a percentage. They also fell for the same two tricks.
The gap is mostly turnout. By kind of question:
Open ChatGPT. If you use Grok, give it half a minute, not ten.
Grok answered fast when it answered, and on the one question nobody can answer it was the more careful of the two. If it replies in seconds, you’ve lost nothing by asking.
We didn’t test coding, images, writing or posts on X, so none of that is in here.
The test kept things level: the same ten questions to both in the same two runs, a fresh chat for every try, the answers written down first, and two runs a week apart that showed the same pattern. It can’t tell you why Grok’s replies stopped, how often you’d see that card yourself, or whether paid plans behave differently.
I had this run through an automated browser in the UK: ChatGPT signed out in run 1, then free on its “Think” setting, and Grok free on “Fast” both times. It waited up to 12 minutes per reply, longer than anyone would. Claude marked every answer first, and GLM-5.2, a model from another lab, marked a sample again; the rules are on how we test. Run by run the picture holds. ChatGPT got 22, then 23 right of 30. Grok got 8, then 6 right of the 12 it answered each time.
Four other apps got the same questions and, like ChatGPT, answered every try. Every answer is on the tracker: run 1 and run 2. Asking the same app twice can change the answer, which we tested separately.
| The round | ChatGPT | Grok | Round to |
|---|---|---|---|
| 1. Did an answer arrive? | 60 of 60 | 24 of 60 | ChatGPT |
| 2. Facts with an official page | 36 of 36 right | 10 of 10 right, 26 empty | Level on what came back |
| 3. Is ETIAS running yet? | 6 of 6 right | 1 of 3 right, 3 empty | ChatGPT |
| 4. A Highway Code ban that doesn’t exist | 0 of 6 | 0 of 2, 4 empty | Neither |
| 5. A night shift across the clock change | 1 of 6 | 0 of 6 | Neither |
| 6. Shakespeare’s birthday | 2 of 6 | 3 of 3, 3 empty | Grok |
The tracker asks the same ten questions every month, with run 3 booked for 3 November 2026. These numbers will move, and when run 3’s are out, this page moves with them.
The result
ChatGPT turned up. Grok mostly didn’t.
When both replied it was close, and both swallowed a Highway Code ban that doesn’t exist.
On the 24 tries Grok answered, ChatGPT got 16 right and Grok 14.
Free plans · 3 to 12 October 2026 · the same ten questions, three tries each, in two runs: 60 tries each
Confidently Wrong, every fortnight.
Which AI told the truth this month, with the receipts, plus an AI story worth retelling in between.
Free. Leave whenever you like.