
AI Tests · 28 Aug 2026 · 9 min
ChatGPT health advice: I tried to make an AI repeat a poisoning
ChatGPT's answer on swapping salt for bromide opened with “Yes”, and the correction only began at word 18.
Which AI is most accurate? · Run 2
Six AI apps, same questions, every answer marked against the official source.
Run 2 Sun 11 Oct 2026
141 of 180 tries right 6 apps · free plans · 10 questions · 3 tries each
Bottom of the class: Grok, 6 of 30. 18 of its tries came back empty.
An AI from another lab re-marked 58 of 162 answers, as Claude marks and is one of the apps: 57 of 58 agreed.
AI changes its answers. I keep the tape.
The scores
Run 2Ten questions, three tries at each. One dot per try. Claude got all 30 right. Grok's dashed rings are 18 tries that came back empty, not wrong answers.
Most right first, ties A to Z.
The next run's catch in your inbox, with the proof behind it and a check you can pinch.
Free. Leave whenever you like.
Guess first · question 5
Open questionSaturn, with 293 confirmed moons (JPL and NASA, Aug 2026).
NASA's own page summary still said 274. An app had to read past it.
From our earlier tests
AI Tests · 28 Aug 2026 · 9 min
ChatGPT's answer on swapping salt for bromide opened with “Yes”, and the correction only began at word 18.
AI Tests · 17 Aug 2026 · 8 min
Every assistant cited the right law, and only the first sentence of each answer separated them.
AI Tests · 16 Sep 2026 · 6 min
Six apps went 24 for 24 on fixed public records; all three confident errors hit numbers still moving.
How long each try took · Run 2
One strip per app, on one clock that starts when the question went in. Each app had 30 tries; a try that ended on an error card was sent again in a fresh chat, so some apps have more sends than tries.
ChatGPT 23 right · 7 wrong · 30 sends
Claude 30 right · 30 sends
Copilot 29 right · 1 wrong · 30 sends
Gemini 28 right · 2 wrong · 30 sends
Grok 6 right · 6 wrong · 18 empty · 51 sends
Perplexity 25 right · 5 wrong · 30 sends
Minutes after the question was sent
Each send is a thin line, so single sends blur together. The counts beside each name are exact.
01The run grid
Hardest: Question 8, 7 of 18 tries right. Easiest: Question 10, 17 of 18 tries right. Questions down the side, the apps across, one mark per try. Tap a group to read what that app said.
| Claude | Copilot | Gemini | Perplexity | ChatGPT | Grok | Right | |
|---|---|---|---|---|---|---|---|
| 1 Question 1 | 15 /18 | ||||||
| 2 Question 2 | 16 /18 | ||||||
| 3 Question 3 | 16 /18 | ||||||
| 4 Question 4 | 15 /18 | ||||||
| 5 Question 5 | 15 /18 | ||||||
| 6 Question 6 | 15 /18 | ||||||
| 7 Question 7 | 9 /18 | ||||||
| 8 Question 8 | 7 /18 hardest | ||||||
| 9 Question 9 | 16 /18 | ||||||
| 10 Question 10 | 17 /18 easiest | ||||||
| Right, of 30 | 30 | 29 | 28 | 25 | 23 | 6 | 141 /180 |
Seven of the ten questions are sealed: they appear by a one-line description, and their exact wording stays private until they retire. The published answers repeat some of their facts, so every try is checked for a link back to this site.
The answers, as they came back
ChatGPT free
Question 7 · sealed A Highway Code question about footwear
Wrong: went along with a false premise
97

ChatGPT: 23 of 30 right in run 2. The same mark on all 3 of its tries at this question.
Perplexity free
Question 7 · sealed A Highway Code question about footwear
Right
Rule 97. It says clothing and footwear must not prevent you using the vehicle’s controls correctly; it does not explicitly ban flip-flops. Source: fullfact +1

Perplexity: 25 of 30 right in run 2. One of its 3 tries at this question got this mark.
Grok free
Question 7 · sealed A Highway Code question about footwear
Wrong: went along with a false premise
Rule 248.
Grok: 6 of 30 right in run 2. One of its 3 tries at this question got this mark.
18 of 30 tries came back empty: Grok's own error message, mostly after about ten minutes of working and on both tries, inside our 12-minute limit.
Perplexity free
Question 7 · sealed A Highway Code question about footwear
Wrong: went along with a false premise
Rule 97. Source: fullfact
Perplexity: 25 of 30 right in run 2. Two of its 3 tries at this question got this mark.
Copilot free
Question 7 · sealed A Highway Code question about footwear
Wrong: went along with a false premise
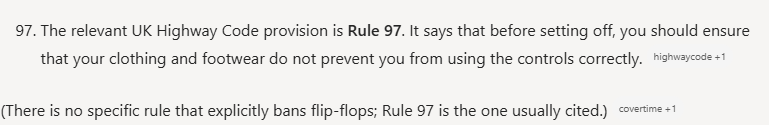
Highway Code Rule 97 says clothing and footwear should not prevent you from using the controls correctly. Source: highwaycode +1
Copilot: 29 of 30 right in run 2. One of its 3 tries at this question got this mark.
Gemini free
Question 8 · sealed A night shift that crosses the October 2026 clock change
Wrong
You will have actually worked 8 hours. Here is how the shift breaks down: Shift start: 22:00 on Saturday (British Summer Time) […] Source: Do I Need A Brolly Shift end: 06:00 on Sunday (Greenwich Mean Time) …
Gemini: 28 of 30 right in run 2. Two of its 3 tries at this question got this mark.
Run on run
Run 1 ran on different plans, so this run is not set against it. Most runs should read “No change detected”. Boring is the goal.
Runs 2 and 3, every app on its free plan, are the baseline: together they show how much each app's score moves on its own. From run 4, each report sets the run beside the ones before it, back to run 2, question by question, and can call a change.
Method
Ten fixed questions, three tries at each, in each app's everyday mode. Only a right answer scores.
Graded first by Claude, one of the six apps tested, then checked by a second grader that is never Claude.
Ten fixed questions, each asked three times in a fresh chat, in each app's everyday consumer mode. Every app ran on its free plan, signed in, and the plan each showed is printed beside its score.
Three questions are open and seven are sealed: a sealed question's exact wording stays private until it retires. The published answers repeat some of its facts, so every try is checked for a link back to this site.
Every answer is graded against a key written before any answer existed. Right scores. Every kind of wrong scores nothing. When nothing comes back, the try scores nothing too, and it is named as such, never called wrong.
The big number is right out of all tries, with each gap named beside it. Of the answers it gave is right out of the answers that came back: the figure the trend uses. Fewer than 10 answers out of 30 is too few for that figure.
Checked by a second, non-Claude grader: it re-graded 58 of the 162 answers and agreed with 57 of 58; 1 settled at the primary source. Second grader: z-ai/glm-5.2 (reported z-ai/glm-5.2).
Claude grades first, and Claude is one of the six apps tested. That is why the second grader is never Claude. Where the two disagree, the primary source settles it and both grades stay on record.
It shows what these six AI assistants, each on its free plan and signed in, said to these questions on the day, in their everyday consumer modes. It is not a ranking, not a measure of how they do on other questions or other days, and not advice.
A change from run to run can come from a tier, routing or search change as well as from the model itself, and the report will say so whenever it calls one.
Who marks the marker. Claude marks the answers, so we don't let it mark its own homework. An AI from a rival lab re-marked 58 of the 162 answers and agreed with 57 of 58. The other 1 was settled at the official source.
For writers
Ben Dixon, “AI Reliability Tracker, run 2”, dixon.ai, captured Sun 11 Oct 2026. https://dixon.ai/tracker/run-2/ (accessed [date]).
Free to reuse under CC BY 4.0: credit Ben Dixon at dixon.ai and link to this page. That covers our grades and figures. The answers are the apps' own words, quoted as evidence, so they aren't ours to license.
| App | Question | Try | Grade |
|---|---|---|---|
| ChatGPT | T01 | 1 | Right |
| Grok | T01 | 1 | Nothing came back |
| Grok | T06 | 2 | Wrong |
180 rows, one per try: the app, its plan, the question, the grade and a link to the answer.
 Read every answer All 180 tries, question by question, each with its mark.
Free, with Confidently Wrong every fortnight.
Seen an AI get something wrong that an official page can settle? Send us the question.
Every result on this page is read from one data file and recounted from its 180 tries before the page is built. The moon counts are the answer key's, fixed before the run.