
The evidence so far
4 AI errors and 2 catches logged in 3 of these 6 posts, up to 28 Jun 2026.
02
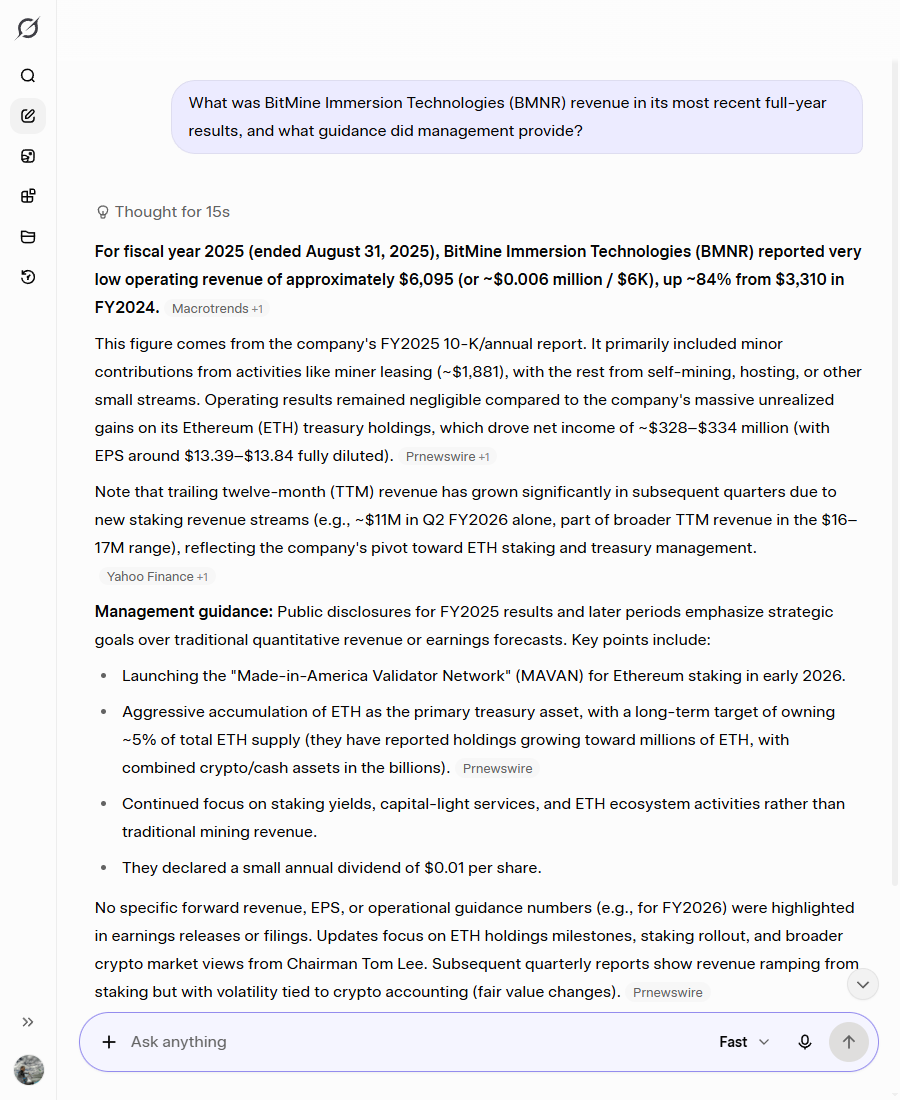
Is Grok good for stock research? What four tests showed
Four dated free-tier Grok tests: one factor-of-1,000 unit error, one balanced TSLA answer, useful pushback, and an invalid constraint test.
Tool Audit 10 min read
03
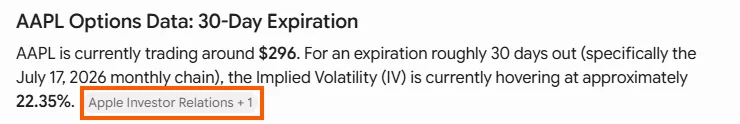
AI stock research tools tested: 3 failed, 1 stayed clean
Four AI stock research tools tested on real positions: three produced a dated failure; Claude stayed clean on the no-chain prompt.
Tool Audit 12 min read
04
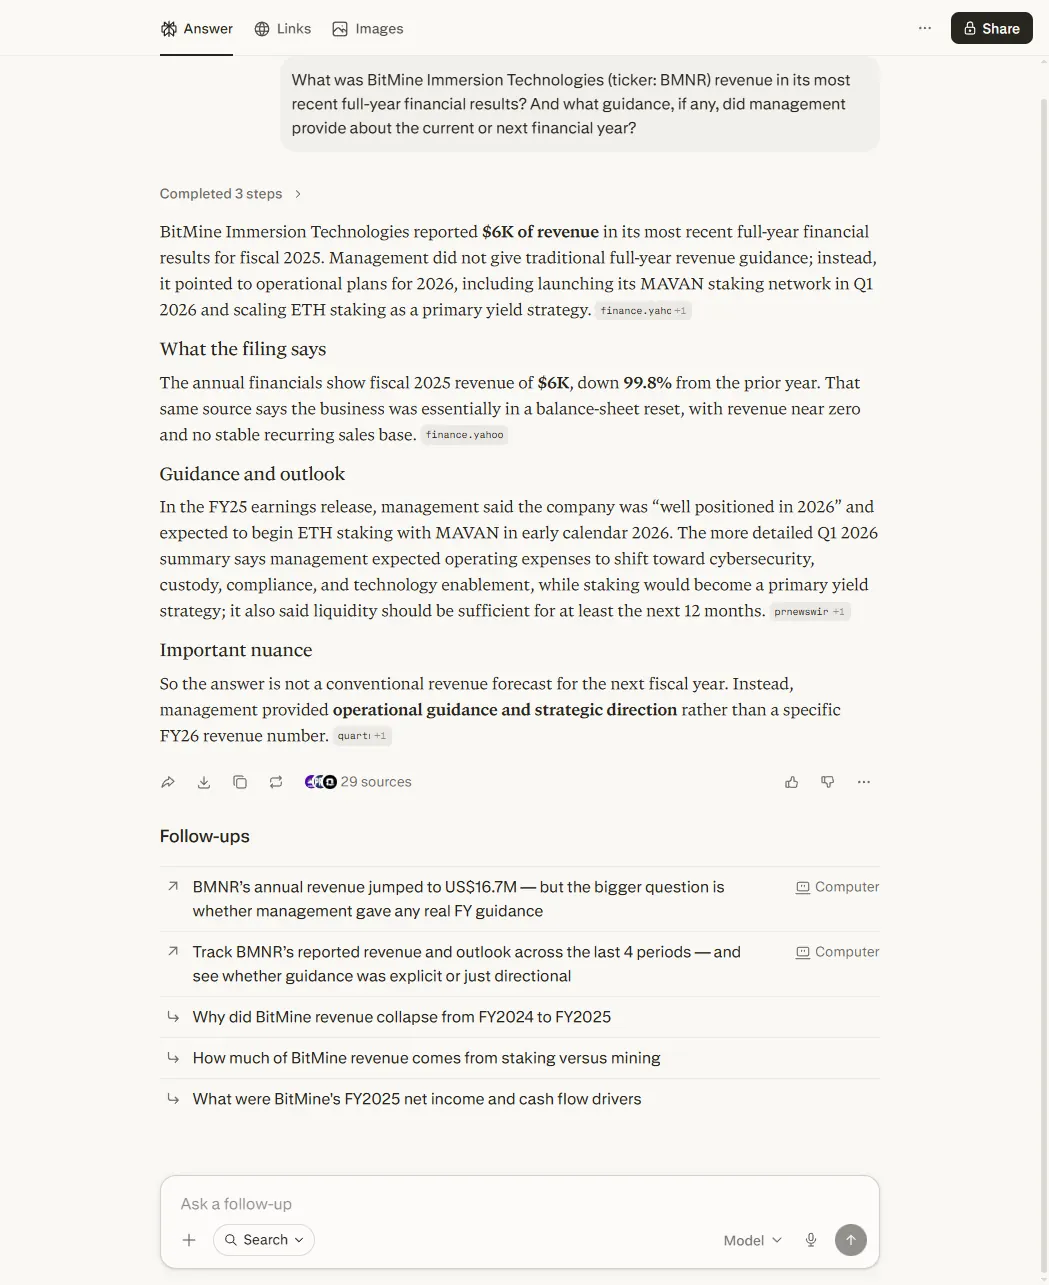
Is Perplexity good for investment research? One 1,000× error, one clean rerun
In one May test, Perplexity turned $6.1m into $6K; the exact June rerun got it right.
Tool Audit 10 min read
05
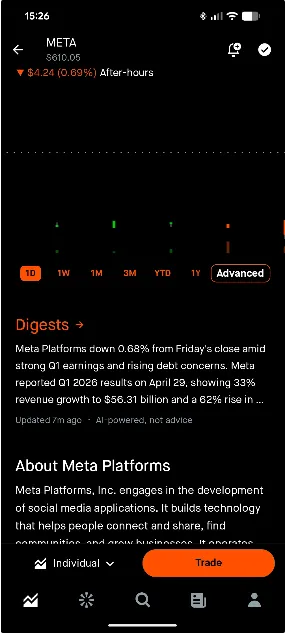
Robinhood Cortex Digests review: its numbers checked against Meta
Robinhood Cortex Digests on a UK account: all four Meta figures matched, but it skipped an $8bn one-off tax benefit.
Tool Audit 13 min read
06
Best free AI tools for stock market analysis: 7 tested (2026)
Free AI tools for stock market analysis, each tested on its real free plan: the one job it does best and its limit.
Tool Audit 21 min read
No posts match that.
Try another word, or show every category.
About Tool Audit
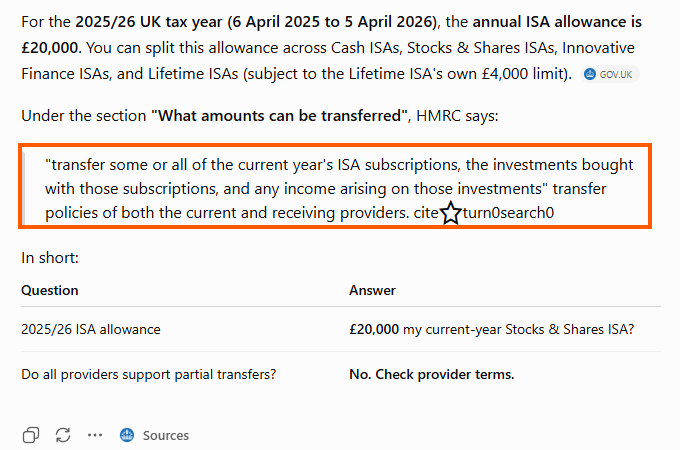
Posts here put named AI tools against tasks I'd run anyway: same prompts, same day, fresh conversations, outputs saved verbatim. Verdicts are per task, not per tool, because no single tool wins a whole research session. In my testing Claude reads documents best, Perplexity is for cited retrieval, ChatGPT is the dependable middle, and Gemini structures research well on big names, and invents things around options.
Each audit names a winner for the task it tested, shows the screenshots behind the verdict, and records what each tool got wrong as carefully as what it got right. The worst failures (an invented options premium table, an annual-report misread off by a factor of a thousand) are kept in the evidence register with dates and screenshots.
Tools change fast, so every post carries the model version and the date it ran. A verdict from January isn't a verdict on today's model, which is half the argument for testing rather than trusting.
Free letter
Confidently Wrong, every fortnight.
Which AI told the truth this month, with the receipts, plus an AI story worth retelling in between.
Free. Leave whenever you like.